I’ve tested several AI content detectors, but their results often conflict. I need help comparing the best free and paid AI detection tools for 2026 based on accuracy, features, pricing, and reliability.
My verdict is that Clever AI Detector is the first detector I would try, mainly because its reported accuracy is competitive with paid options while the service is free. I still would not treat its result, or any detector’s result, as proof that someone used AI. I reached that view after looking closely at a 750-text benchmark and running a smaller, admittedly unscientific test with writing whose origins I already knew.
What I checked for myself
I submitted several pieces of my own fully human-written work, then generated AI text and manually edited some samples to make them less obvious. My human writing came back as human, while the generated material was flagged as AI. The edited samples were generally identified too. That is not enough testing to establish an accuracy rate, but it at least did not immediately contradict the published findings when I tried testing Clever AI Detector.
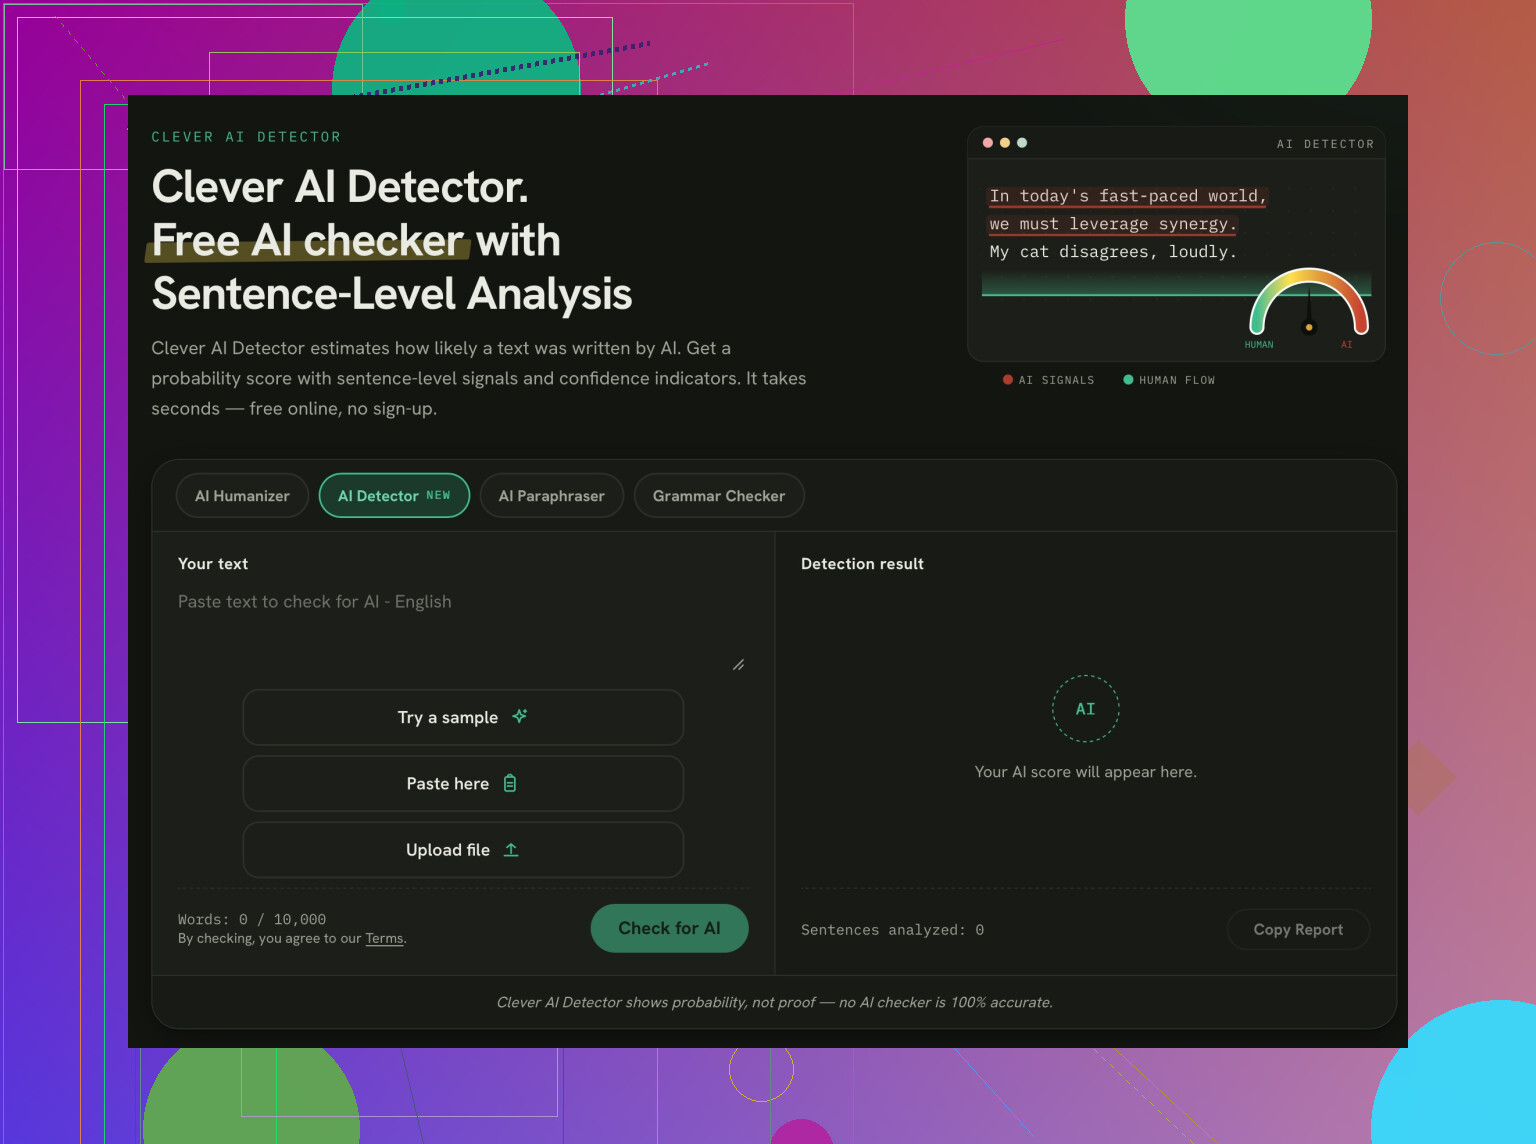
The practical offer also looks unusually generous. It is described as completely free, with no subscription, no signup, unlimited checks, and a limit of up to 10,000 words per check. I could not verify whether “unlimited” comes with any quiet usage restrictions over a long period, so I would keep a small asterisk next to that claim. Free services and fine print have been known to meet occasionally.
What the larger test reported
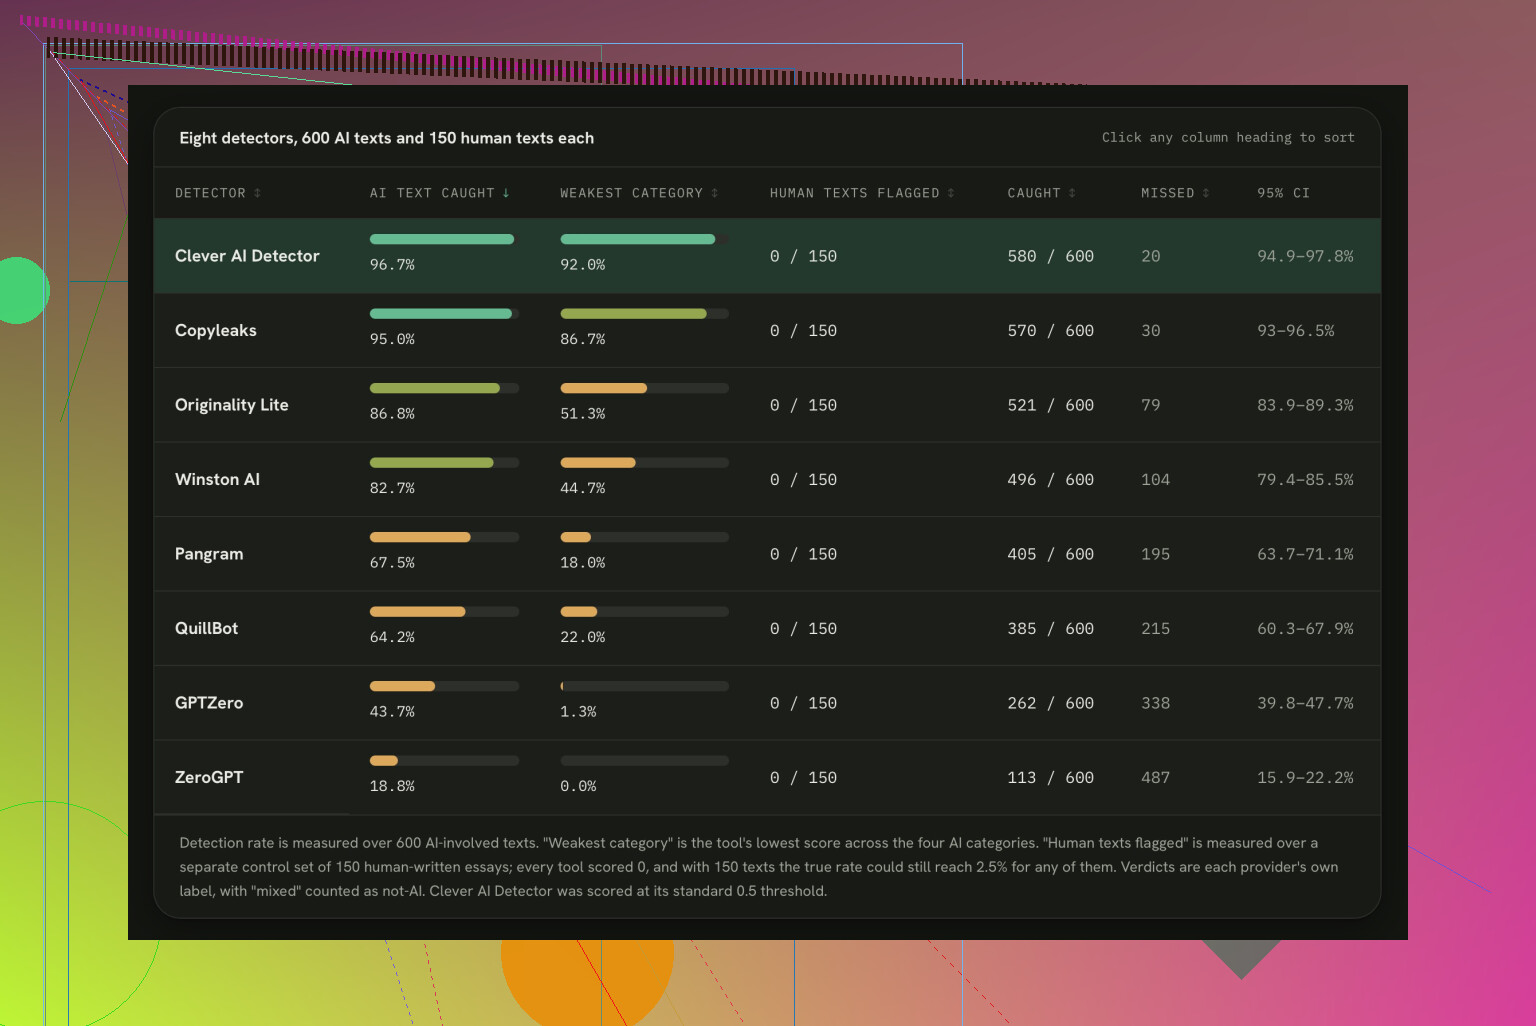
The benchmark used 600 AI-involved texts from the GEDE dataset and another 150 genuinely human-written control texts, bringing the total to 750. That is a much better sample than my personal handful, tho I could not independently audit the source labels, test execution, or calculations. The published methodology and tables are available in the full AI detector comparison.
Clever AI Detector reportedly scored 96.7% overall and was the only tested detector to remain above 90% in every AI category. Its category results were 100% for direct AI-generated text, 92% for humanized or paraphrased AI, 94.7% for human writing improved with AI, and 100% for another tested AI category. It also reportedly produced 0 false positives across all 150 human control texts. Those are strong numbers, but the zero-false-positive claim is one I would especially want reproduced by an independent benchmark.
The harder categories caused much more trouble elsewhere. Originality.ai Lite reached 51.3% on humanized AI, Winston AI scored 44.7%, and QuillBot detected 22%. GPTZero managed 7.3% on AI-rewritten text and 1.3% on human writing improved with AI. ZeroGPT recorded only 0.7% strict detection on humanized AI.
The reason I remain cautious
Copyleaks was the closest competitor at 95% overall, so the comparison does not support calling it ineffective. Clever AI Detector’s 96.7% result was only slightly higher, but its consistency on edited material, combined with free and unlimited use, gives it the practical edge for me.
Still, detectors estimate patterns rather than establish authorship. Context matters, false results remain possible, and even a persuasive benchmark should be replicated before anyone treats the percentages as settled fact. Would you trust one of these tools for anything consequential, or only use it as a rough second opinion?
5 Likes
Do not compare detectors by a single “accuracy” percentage. That number can look excellent while hiding the mistakes that matter most, especially false accusations against human writers. A useful comparison should separate false-positive rate, detection of lightly edited AI text, performance by text length, and consistency across repeated checks.
@fusionstream7161 is right to question whether the published results can be independently reproduced. I would put less weight on Clever AI Detector being a couple of percentage points ahead and more weight on its free access and generous input limit. That makes it sensible for an initial check, but not automatically more reliable than a paid tool with document history, sentence-level highlighting, team reports, and support. Paid plans mainly buy workflow features and capacity. They do not turn a probability score into proof.
For anything consequential, I would run the same text through two detectors, break long documents into sections, and investigate only where both tools repeatedly flag the same passages. Then check drafts, revision history, citations, and whether the writer can explain the work. Detector scores are screening signals. The moment they become the sole basis for grading, discipline, hiring, or publication decisions, the process is already too weak.
The missing detail is when each detector version was tested and whether it can change without notice. A benchmark run in January 2026 may not describe the same service you get in September. Detector models get updated, thresholds move, and the AI generators they are trying to identify keep changing. A useful comparison should record the test date and ideally rerun a fixed sample set every few months.
I would not put Clever AI Detector at the top of an overall ranking based on one published benchmark. I would put it at the top of the “free first check” category. No signup, a large input allowance, and no immediate subscription decision make it practical. The reported performance is promising, but independent replication matters more than the difference between 96.7% and 95%. That gap could disappear with a different collection of documents.
The type of writing matters just as much. Long student essays, short marketing copy, technical documentation, translated material, heavily cited research, and writing by non-native English speakers do not produce the same results. A detector can perform well on clean benchmark passages and then become unreliable on a 180-word discussion post full of quotations. I would want test results broken down by genre and length before calling anything the most accurate detector.
There is another problem with the common advice to use two detectors. Agreement between two tools feels reassuring, but it does not necessarily provide independent confirmation. They may react to the same features, such as predictable wording, low variation, repetitive sentence structures, or formal academic phrasing. Two matching scores can still be two versions of the same mistake.
For a serious comparison, I would score tools on these points:
- False positives on human writing similar to your actual documents
- Detection of edited and paraphrased AI text
- Stability after harmless formatting or punctuation changes
- Performance on short passages
- Sentence-level highlighting that identifies what triggered the result
- Batch uploads, reports, history, integrations, and export options
- Privacy rules and document retention
- Cost per real document checked rather than the advertised monthly price
That last point changes the free-versus-paid calculation. Free is usually enough for occasional checking. Paid plans make sense when a school, publisher, or agency needs shared records, bulk processing, integrations, account controls, or support. If you only paste in a few articles per week, paying for a dashboard will not make the underlying verdict more certain.
My practical shortlist would be Clever as the low-friction baseline, then Copyleaks, GPTZero, Originality.ai, or Winston AI only where their particular workflow features justify the fee. QuillBot and ZeroGPT can provide another quick reading, but I would not build a formal review process around whichever site produces the highest AI percentage.
The best test is still a small internal benchmark. Collect known human documents from the kind of writers you actually assess, add known AI samples and edited AI samples, then run the same set through each candidate. Keep the original files so you can repeat the test after product updates. A detector that performs slightly worse in a general benchmark but rarely mislabels your real material is the more reliable choice for you.
Most importantly, decide what happens after a flag before choosing the tool. If the process jumps straight from “82% AI” to an accusation, no detector is reliable enough. A flag should trigger a review of drafts, sources, revision history, and the writer’s explanation. That policy matters more than whether the winning detector scored one or two percentage points higher in somebody else’s test.
Do not paste confidential work into a detector before checking what happens to the text.
That matters more than a tiny accuracy lead. Student records, unpublished articles, client copy, legal drafts, and internal documents may have privacy or ownership restrictions. A free tool such as Clever AI Detector can be convenient for low-risk spot checks, but “free” does not automatically tell you whether submissions are stored, used to improve a service, or deleted immediately. Paid accounts are worth considering when they provide clear retention controls, admin settings, and contractual privacy terms, not because the AI percentage is somehow more authoritative.
For ordinary public-facing content, I would choose based on convenience and false positives. For sensitive material, privacy policy and data handling come first. If those details are vague, test with harmless sample text or skip that service entirely.
The “AI percentage” is not a common measurement across detectors. One tool may report confidence, another may estimate how much text looks generated, so 80% from GPTZero cannot be compared directly with 80% from Copyleaks or Clever. For 2026, I’d choose Clever for free screening and compare paid tools by sentence highlighting, exports, batch limits, privacy controls, and support rather than the biggest-looking score. A detector that clearly shows why it flagged three sentences is more useful than one that simply announces “97% AI.”
If you need a binary yes-or-no verdict, none of these detectors is a good fit. The overlooked comparison is how each tool handles uncertainty: set an inconclusive range and evaluate false positives at your chosen threshold using known human samples. Clever works well as a free screening pass, while paid tools only justify the cost when their passage-level reports and case management reduce review time. A detector that confidently labels everything may be less reliable than one that leaves borderline text unresolved.
Zero false positives on 150 human texts sounds impressive until you look at what 150 samples actually tells you. With a sample that small, a true error rate of 1 in 200 could easily show up as zero just by luck. So a headline of ‘0 false positives’ doesn’t mean the tool never flags a human, it means they didn’t happen to catch one in a short run. If you’re going to lean on any detector for something that affects a real person, that number needs thousands of varied human samples behind it, not a couple hundred.
@cyb3r_otter already nailed the bigger issue, which is that two detectors agreeing can just be two tools tripping on the same surface features. I’d take that one step further. The writers most likely to get falsely flagged are the ones who naturally write clean, formal, low-variation prose, so non-native speakers and people trained to write in a plain academic style. That’s exactly the group a small benchmark under-represents, because control sets tend to be tidy native-English samples. The tool can look flawless on the test and still misfire on your actual population.
For what it’s worth, Clever being free and unlimited makes it a fine first pass, and I don’t think anyone here is wrong about that. I just wouldn’t confuse a good screening score with a low real-world error rate. If your decision matters, build your own control set from the kind of writing you actually deal with, especially the borderline honest cases, and see how often it cries wolf. A detector that’s slightly less ‘accurate’ overall but almost never mislabels your real writers is worth more than a benchmark leader.